Haystack 2.0 Architectural Guide: Modular Production RAG Pipelines
When building production search and Question-Answering (QA) pipelines over millions of enterprise documents, opaque black-box abstractions lead to latency bottlenecks and difficult debugging.
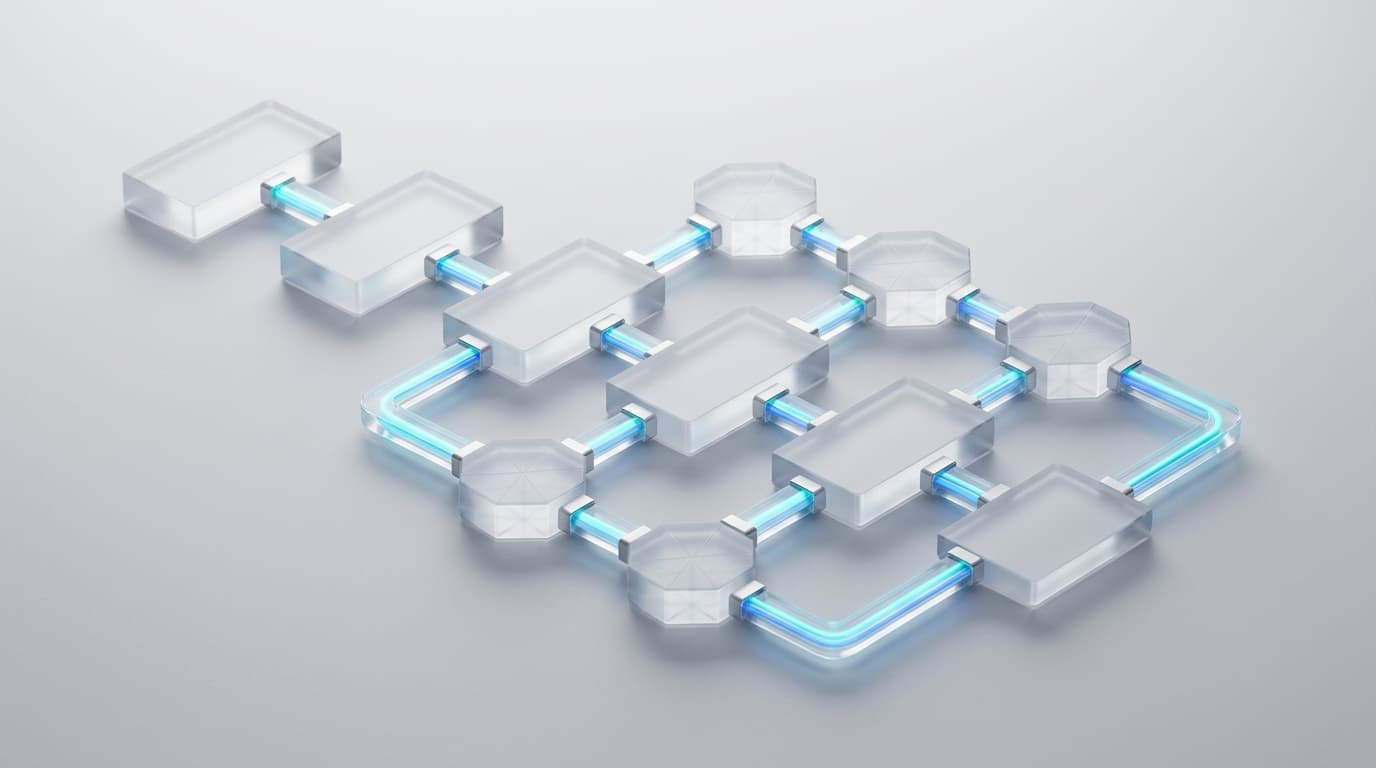
Haystack 2.0 (developed by deepset) is an open-source NLP and search framework built around explicit, directed-graph Pipelines and modular Components. Every component in Haystack 2.0 is a standalone Python class with strictly typed inputs and outputs connected via declarative socket wiring.
1. Core Architecture & Mental Model
Haystack 2.0 structures applications around two foundational primitives:
- 1Components (
@component): Standalone, modular units of processing (such as aDocumentCleaner,SentenceTransformersTextEmbedder, orOpenAIGenerator). Each component declares@component.inputand@component.outputsockets. - 2Pipelines (
Pipeline): A directed acyclic graph (DAG) that routes data between components. Pipelines support branching, loops, and parallel component execution.
2. Installation & Quick Setup
bash
pip install haystack-aiSet your OpenAI API key in your environment:
bash
export OPENAI_API_KEY="sk-..."3. Recommended Production Folder Structure
text
haystack_rag/
├── components/
│   └── custom_cleaner.py    # Custom domain-specific text normalizers
├── pipelines/
│   ├── indexing.py          # Ingestion & document embedding DAG
│   └── query.py             # Retrieval & QA generation DAG
├── stores/
│   └── document_store.py    # Qdrant / OpenSearch / InMemory store setup
└── main.py
4. Complete, Runnable Starter Project in Python
Below is a complete, standalone Haystack 2.0 RAG pipeline demonstrating document store population, component connection, and query execution:
python
from haystack import Pipeline, Document
from haystack.document_stores.in_memory import InMemoryDocumentStore
from haystack.components.retrievers.in_memory import InMemoryEmbeddingRetriever
from haystack.components.embedders import OpenAITextEmbedder, OpenAIDocumentEmbedder
from haystack.components.builders import PromptBuilder
from haystack.components.generators import OpenAIGenerator

# 1. Initialize Document Store
document_store = InMemoryDocumentStore()

# 2. Ingest Sample Documents with Embeddings
sample_docs = [
    Document(content="Haystack 2.0 uses explicit socket connections between components in a Pipeline DAG."),
    Document(content="PromptBuilder combines Jinja2 templating with retrieved document context."),
]

doc_embedder = OpenAIDocumentEmbedder(model="text-embedding-3-small")
docs_with_embeddings = doc_embedder.run(documents=sample_docs)["documents"]
document_store.write_documents(docs_with_embeddings)

# 3. Define Jinja2 Prompt Template
template = """
You are a technical documentation assistant. Answer the question based on the provided documents:

Context:
{% for doc in documents %}
- {{ doc.content }}
{% endfor %}

Question: {{ question }}
Answer:
"""

# 4. Assemble the Query Pipeline DAG
pipeline = Pipeline()
pipeline.add_component("text_embedder", OpenAITextEmbedder(model="text-embedding-3-small"))
pipeline.add_component("retriever", InMemoryEmbeddingRetriever(document_store=document_store, top_k=2))
pipeline.add_component("prompt_builder", PromptBuilder(template=template))
pipeline.add_component("llm", OpenAIGenerator(model="gpt-4o-mini"))

# 5. Connect Component Sockets
pipeline.connect("text_embedder.embedding", "retriever.query_embedding")
pipeline.connect("retriever.documents", "prompt_builder.documents")
pipeline.connect("prompt_builder.prompt", "llm.prompt")

# 6. Execute Pipeline
if __name__ == "__main__":
    query_text = "How are components connected in Haystack 2.0?"
    result = pipeline.run({
        "text_embedder": {"text": query_text},
        "prompt_builder": {"question": query_text},
    })

    print(f"Query: {query_text}\n")
    print(f"Generated Answer:\n{result['llm']['replies'][0]}")
5. Architectural Tradeoffs Matrix
| Feature | Monolithic RAG Chains | Haystack 2.0 |
|---|---|---|
| Pipeline Transparency | Nested black-box function calls | Explicit Graph Socket Wiring (pipeline.connect) |
| Component Isolation | Tight framework coupling | Decoupled Python classes with typed sockets |
| Search Engine Integrations | Basic vector wrappers | Deep OpenSearch, Elasticsearch, Qdrant support |
| Branching & Loops | Complex conditionals | First-Class Pipeline Branching & Evaluation |
6. When to Use vs. When to Avoid
Choose Haystack 2.0 When:
- You are engineering production-scale semantic search, document retrieval, and Question-Answering (QA) pipelines.
- You demand strict architectural clarity where every intermediate transformation step is explicitly mapped in a Pipeline graph.
Avoid Haystack 2.0 When:
- You are building real-time Next.js frontend streaming interfaces (use Vercel AI SDK instead).